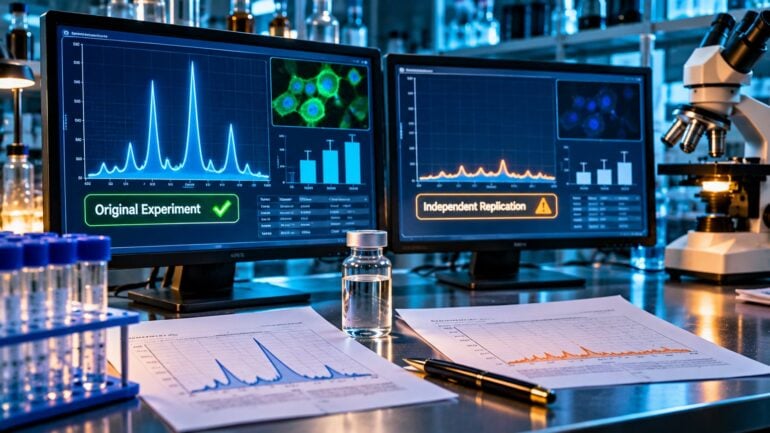
A research team finishes an experiment and discovers an unexpected biological signal. The initial data look convincing. The charts show a clear difference between the experimental groups, the statistical analysis suggests a meaningful result, and the researchers begin discussing what the discovery could mean for future studies.
Months later, another laboratory attempts to examine the same scientific question. Its results do not agree with the original findings. The researchers examine their instruments, repeat their calculations, and review their experimental procedures. Yet the anticipated effect remains uncertain.
Does that mean the first laboratory failed? Not necessarily. Scientific investigation is more complicated than a single successful experiment, and disagreement between studies can reveal important differences in methods, materials, assumptions, or experimental conditions.
The real test of scientific progress is not whether an initial discovery generates excitement. It is whether the evidence remains convincing when researchers question the result, examine its limitations, and investigate it independently.
In biomedical and peptide research, this distinction matters because preliminary observations can attract attention long before the necessary evidence exists to establish broader conclusions.
Why One Successful Experiment Is Only the Beginning
Scientific discoveries frequently begin with an observation that researchers did not anticipate. A molecular interaction may appear stronger than expected, a laboratory measurement may reveal an unusual pattern, or an experimental group may produce a result that differs from its controls.
These observations can provide valuable starting points for further investigation.
However, an initial result does not establish that the observation will occur consistently under other conditions. Every experiment contains sources of uncertainty, including measurement variation, biological differences, and limitations in experimental design.
A finding may also be influenced by variables that researchers did not initially recognize. These could include differences between laboratory materials, environmental conditions, analytical procedures, or the characteristics of the experimental model.
The National Institutes of Health emphasizes scientific rigor as an essential part of biomedical research. Its guidance describes rigorous research as applying scientific methods to support unbiased experimental design, analysis, interpretation, and reporting.
The objective is not to discourage interesting discoveries. It is to ensure that conclusions remain proportionate to the evidence supporting them.
A promising result becomes more scientifically useful when other researchers can examine how it was produced and determine whether the finding holds under appropriately comparable conditions.
Reproducibility and Replicability Are Not Exactly the Same Thing
Two related terms often appear in discussions of scientific reliability: reproducibility and replicability.
They are sometimes used interchangeably, but the National Academies of Sciences, Engineering, and Medicine distinguished them in its 2019 report, Reproducibility and Replicability in Science.
Under the report’s definitions, reproducibility concerns whether researchers can obtain consistent computational results using the original data, code, analytical procedures, and conditions.
Replicability concerns whether a new study addressing the same scientific question can obtain consistent results using newly collected data.
These are related but distinct forms of scientific confidence.
For example, a second analyst might successfully reproduce the calculations in a published study using its original dataset. That result supports the consistency of the computational analysis.
However, it does not establish that a completely new experiment would produce the same biological findings.
Conversely, a laboratory might obtain similar observations in a new experiment even when the original publication does not provide enough computational information for its analysis to be reproduced precisely.
Distinguishing these questions helps researchers identify what has actually been confirmed and what still requires investigation.
The Experimental Control That Can Change the Entire Conclusion
Controls are central to determining whether an observed result can reasonably be attributed to the variable being investigated.
Without appropriate controls, researchers may struggle to distinguish the effect of an experimental condition from ordinary variation or other influences.
Imagine a laboratory comparing two groups of cultured cells. One group receives an experimental material, while the other serves as a comparison.
If the groups differ in additional ways, such as incubation conditions or sample-handling procedures, the results may not isolate the variable the researchers intended to test.
A strong experimental design attempts to identify and minimize such differences.
Control selection depends on the research question. Negative controls, positive controls, reference materials, and other comparison conditions can each serve different purposes.
The presence of a control group alone is not sufficient. Researchers must establish whether the chosen controls address the most important alternative explanations.
When a finding disappears after a better control is introduced, the result may reveal a weakness in the original interpretation rather than a failure of the entire scientific process.
Recognizing such weaknesses can prevent later studies from building on unsupported assumptions.
Why Randomization and Blinding Strengthen Scientific Findings
Scientific bias does not always involve deliberate misconduct. Researchers can unintentionally influence experiments through decisions made during sample allocation, measurement, or interpretation.
Randomization is one method used to reduce systematic differences between experimental groups.
When appropriate for a study, assigning experimental units randomly helps reduce the likelihood that known or unknown factors consistently favor one group.
Blinding addresses a different problem. It can limit the influence of expectations by preventing relevant participants or researchers from knowing particular group assignments during specified stages of an experiment.
The NIH identifies randomization, blinding, and suitable experimental controls as important practices for reducing bias in biomedical research.
These techniques are not equally applicable to every experiment. Some laboratory procedures make complete blinding impractical, and certain observational studies cannot use random assignment.
In those cases, researchers should explain the limitations and use other justified methods to reduce bias.
Scientific rigor involves selecting appropriate safeguards for the actual research design, rather than applying the same checklist mechanically to every study.
Why Peptide Research Requires Separate Evidence for Separate Claims
Research involving peptides can address several different scientific questions.
A chemical analysis may investigate molecular identity, composition, or stability. A cell-based experiment may examine a response under specific laboratory conditions. Animal research may evaluate a biological hypothesis in a defined model.
These studies do not automatically establish that a compound produces a useful or safe effect in humans.
The difference matters because scientific discussions sometimes combine early laboratory findings with broader statements that the original experiments were not designed to support.
For example, an analytical technique may provide evidence that a sample contains a particular molecular structure. That result says something about chemical characterization, not clinical effectiveness.
Likewise, a measurable response in cultured cells may be an interesting biological observation without demonstrating an outcome that matters to patients.
Educational information from Peptides Henderson can be considered as background reading on research topics, but general educational material should not be confused with independent verification of a particular laboratory finding.
Researchers should examine the original studies and distinguish between molecular characterization, preclinical observations, and controlled human clinical evidence.
That distinction is essential when deciding what a promising experiment actually establishes.
The Sample Size Problem Behind Apparently Impressive Results
An experiment involving a small number of independent observations can sometimes produce a striking result.
However, small samples often provide limited information about the stability and precision of an estimated effect.
Results may vary substantially when an experiment is repeated with additional independent observations.
Researchers therefore need to consider whether their sample size is appropriate for the scientific question, anticipated variation, and analytical approach.
For hypothesis-testing studies, sample-size planning may involve an assessment of statistical power, the effect size of interest, and expected variability.
It is also important to identify the true experimental unit. Measuring the same sample repeatedly does not necessarily create the same number of independent observations as measuring independently prepared samples.
The ARRIVE 2.0 guidelines for reporting animal research emphasize documenting experimental units, group sizes, sample-size decisions, and the number of observations included in analyses.
These guidelines specifically concern animal research, but the broader distinction between independent observations and repeated technical measurements is relevant across many experimental disciplines.
A convincing figure should therefore be evaluated alongside the study’s sampling structure and uncertainty, not in isolation.
Why Researchers Should Define Success Before Collecting Results
Researchers sometimes measure many outcomes within a single experiment. Some measurements may support the original hypothesis, while others show little difference between groups.
When investigators examine numerous possible outcomes and emphasize only the most favorable result, readers may receive an incomplete picture.
This risk becomes more serious when the primary outcome was not specified before the analysis.
Predefining research questions, outcome measures, and important analytical decisions can help distinguish planned tests from exploratory findings.
Exploratory analysis remains valuable because unexpected patterns can generate new hypotheses.
The important distinction is whether a finding was predicted and tested under a predefined plan or discovered after examining the available data.
Both activities can contribute to scientific progress, but they provide different kinds of evidence.
Transparent reporting allows readers to evaluate that difference rather than assuming every statistically interesting result was anticipated.
What Happens When Two Laboratories Reach Different Conclusions
A failure to obtain the same result in a second experiment should trigger investigation rather than an immediate assumption that one laboratory is dishonest or incompetent.
Biological systems contain genuine variability. Differences in experimental materials, sample preparation, analytical instruments, cell models, or environmental conditions may affect outcomes.
Researchers also need to consider whether both studies genuinely addressed the same scientific question.
Small methodological changes can sometimes alter what a test measures.
The National Academies’ report explains that a single unsuccessful replication does not conclusively invalidate an original finding.
Similarly, one successful replication does not guarantee that the original conclusion is universally correct.
The appropriate interpretation depends on the uncertainty surrounding both studies and how closely their conditions correspond.
Disagreement can therefore become an opportunity to identify hidden variables or refine a scientific hypothesis.
The strongest response is a transparent examination of methods and evidence, not an attempt to protect the reputation of a particular result.
Why Transparent Reporting Is a Competitive Advantage for Research Organizations
Research organizations operate in environments where credibility depends on the quality of their evidence.
A team that reports limitations clearly may appear less dramatic than one announcing a major discovery without qualification. However, transparent reporting allows other researchers to evaluate the work more meaningfully.
Useful reporting explains the experimental design, sample size, controls, analytical procedures, exclusions, uncertainty, and potential sources of bias.
It also distinguishes original measurements from interpretations and identifies where further investigation is required.
Organizations publishing scientific educational content can apply the same principle to their communication.
An overview of Peptides Henderson and its educational background may help readers understand the website’s stated purpose, but it should not be treated as independent proof of analytical capabilities, laboratory certifications, or product-specific scientific claims.
Those claims require evidence directly relevant to the statement being made.
Clear boundaries between organizational information and experimental evidence help readers avoid drawing unsupported conclusions.
The Difference Between a Significant Result and a Meaningful Discovery
A statistically significant result does not automatically represent a scientifically important discovery.
Statistical significance addresses a particular question within a defined analytical framework. It does not independently establish the size, practical relevance, or biological importance of the observed difference.
A very small effect might reach a conventional statistical threshold in a sufficiently large dataset while remaining of limited practical importance.
Conversely, an experiment with few observations may fail to reach a threshold despite producing an estimate that warrants further investigation.
Researchers should therefore evaluate effect sizes, uncertainty intervals, study limitations, and consistency with other evidence.
In biomedical research, it is also essential to distinguish laboratory measurements from outcomes relevant to human health.
A change in a biomarker may support a hypothesis without proving that a treatment improves an actual clinical outcome.
Scientific interpretation requires understanding what was measured and whether the measurement directly supports the conclusion being proposed.
Five Research Habits That Make Results Easier to Trust
Several practical habits can strengthen the reliability of experimental research and make findings easier for other scientists to evaluate.
- Define the research question clearly. Specify what the experiment is designed to test and identify outcomes that can meaningfully address that question.
- Choose appropriate controls. Consider alternative explanations and select comparisons that help distinguish the experimental variable from confounding influences.
- Document methods and materials. Preserve enough information about experimental procedures, sample identities, and analytical methods to support meaningful review.
- Report uncertainty and exclusions. Explain sample-size decisions, variability, missing observations, and reasons for excluding data.
- Encourage independent investigation. Treat new evidence and unsuccessful replications as opportunities to examine the boundaries of the original conclusion.
None of these practices guarantees that every experiment will produce a correct answer.
Together, however, they make scientific conclusions more transparent and reduce the likelihood that an attractive but fragile result becomes accepted without sufficient scrutiny.
Why Research Readers Should Know Where to Ask Questions
Scientific communication improves when readers can identify the origin of a claim and seek clarification about its meaning.
A research website’s contact page for additional information may provide a channel for asking about published educational content.
That communication channel does not independently establish laboratory competence, research affiliations, or verification of individual scientific findings.
Readers should request appropriate sources when encountering claims that depend on experimental evidence.
Relevant questions might include which study produced the result, what experimental model was used, and whether the reported conclusion reflects the original publication.
When scientific information is presented responsibly, uncertainty can be acknowledged without making the explanation unhelpful.
Knowing the limitations of a study is often as important as understanding its most interesting findings.
The Real Measure of Scientific Success Is Evidence That Survives Scrutiny
Scientific progress rarely follows a perfectly predictable path. An exciting discovery may become the foundation of an important research program, or later experiments may reveal that the original interpretation was incomplete.
Neither outcome makes the process meaningless.
Careful controls, independent replication, transparent reporting, and appropriately defined outcomes allow researchers to distinguish promising observations from conclusions supported by stronger evidence.
For peptide research and other biomedical disciplines, this discipline helps prevent preliminary results from being confused with demonstrated human benefits.
It also makes scientific communication more useful to readers who need to understand both the possibilities and limitations of emerging research.
The best research organizations do not define success by how quickly a result becomes a headline. They establish processes that allow findings to be tested, challenged, corrected, and refined.
A discovery earns lasting scientific value when its evidence remains understandable and credible after the initial excitement has passed.